
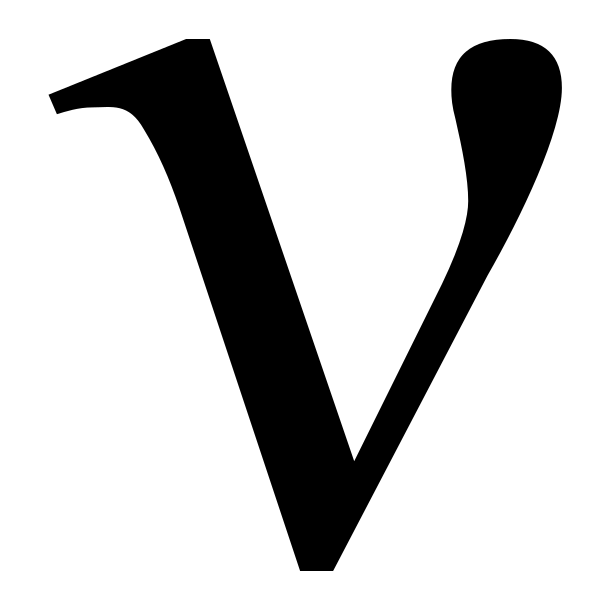
 Nu
allow,
deny, or require_approval.
A replayed step returns its recorded outcome without consulting policy again, so
editing a bundle does not re-gate work an execution has already done.
Attach a bundle inline with policy: or from a file with policy_file: in a
provisioning manifest. Set one or the other, not both, and write the
policy_file path relative to the manifest. You can also load a bundle over the
admin API with POST /v0/policies/{agent_id}.
The kernel compiles a bundle before storing it, so a malformed one is rejected
with a validation error at registration rather than failing later at a step. An
agent with no bundle is unrestricted, in production as much as in dev.
Bundle format
Evaluation
Rules are evaluated top to bottom in the order they appear in the bundle. The first rule whosewhen block matches wins, so put the specific rules above the
broad ones. If nothing matches, default_action applies, and any value other
than allow means deny. Every rule needs an id, unique within the bundle.
Unknown keys are rejected, so a bundle carrying a key no rule field claims will
not load.
default_action covers tool_call and llm_call steps. An unmatched local
step is allowed whatever default_action says. To govern one, match it with a
rule on target or step_kind: local.
Match conditions
All fields present in a rule’swhen block must match (AND). Omitted fields are
not checked.
Argument predicates
arguments is a map of argument key to predicate. The key must be present in
the call’s arguments, and every constraint listed under it must pass. Values are
compared as strings.
A predicate needs at least one constraint. An empty one (command: {}, or
command: {equals: ""}) is rejected at load, because a constraint that matches
any value would silently widen the rule.
A key with dots is a path into nested objects, so
config.environment reads
environment inside the config object. The rule does not match when a
segment is missing or its value is not an object; arrays are not traversed. An
argument whose own name contains a dot takes precedence over the path it spells.
{"force": true} compares as {"force":true}.
History conditions
history is a list of clauses about the steps policy allowed earlier: steps that
started, whether they succeeded, failed, or are still running. Every clause must
hold.
The call being decided counts toward a clause it matches, unless the clause has
result. A clause with at_most: 3 on its own target allows the third call and
refuses the fourth, and a sum includes the amount being requested. Steps still
running count, so parallel calls cannot pass a cap before earlier ones finish.
Denied steps and steps awaiting approval do not count.
A clause with the default bound requires that something happened; at_most: 0
requires that it did not. Either can carry the decision:
sum argument is missing or not a number fails the
clause. Write a cap as an allow rule above a stricter one, so such a step
falls through to the stricter rule:
history_unavailable under the rule being evaluated.
The client names the session, so a new session starts with empty history. A
session-scoped count or sum therefore limits a cooperating client; for a hard
ceiling, use a rate limit with per_what: agent or global. A
clause that requires something to have happened denies in a new session.
Rule decisions
A rule’sthen block carries the decision and its options:
Every policy decision event (
step.allowed, step.denied,
step.awaiting_approval) carries the matched rule_id in its payload, which is
what makes the log auditable. rule_id is the matched rule’s own id and is
not settable from the bundle. A decision that came from somewhere other than a
rule gets a fixed id. The default_action fallthrough is default, an
unmatched local step is local, an agent with no bundle is permissive, and a
stored bundle that will not compile is bundle-error.
Approvals
When a rule returnsrequire_approval, the kernel records
step.awaiting_approval and approval.requested, creates an approval, and
moves the execution to blocked. A human grants or denies it through the
approvals API and the execution resumes. See Events and
Approvals.
decided_by is the authenticated caller: admin for the deployment token,
service:<key id> for an API key, or user:<claim> for an
OIDC user. A caller holding the approvals:delegate
scope may name the approver instead, and the approval records that caller in
asserted_by. approvers entries match decided_by exactly, and a
group:<name> entry matches an OIDC user in that group. A name supplied through
approvals:delegate matches only exact entries.
Rate limits
A rule can cap how often it fires. The bucket is keyed on the rule’srule_id
and the scope in per_what, so two rules never share one.
per_what: session shares the bucket across a session’s executions, and falls
back to the execution for one without a session. per_what: subject shares it
across every execution acting for one subject, and falls back the same way.
A step over the limit comes back as rate_limited rather than a policy denial.
Put a hard ceiling in a deny or require_approval rule instead.
With max_wait set, a limited step parks. The submit returns blocked, the
execution stays running, and the kernel re-dispatches once the bucket refills.
An execution parks only once. If the step is still over the limit on the retry,
or the wait would run longer than max_wait, it is refused.
Token budgets
A rule can cap the LLM tokens an execution or a session spends. The cap applies only to a rule that decidesallow.
scope: session
it sums every execution in the session, including failed ones, and falls back to
the execution for one without a session. Only llm_call steps
record usage, so nothing else moves the meter.
The check runs before the call, so the step that crosses the limit still runs. A
response with no parseable usage never advances the meter, most often an
OpenAI-style stream requested without stream_options.include_usage, and
rebuno_llm_usage_missing_total counts those. If the kernel cannot read the
execution’s usage at all, it lets the step through.
Judge
A rule that decidesjudge hands the call to a decision model, which picks
allow, deny, or require_approval. It suits tools whose calls are too varied
to list as predicates, such as a shell. Text in the arguments can steer the
model, so put deny rules for commands known to be dangerous above it.
Without
question, the model answers: “Should tool_call run automatically, be
blocked, or wait for a human to approve it?” The default criteria are:
The model is any HTTP API that returns a probability for each decision. A YAML
file named by
REBUNO_JUDGE_CONFIG (Deployment)
describes the request and where the probabilities are in the response. Without
it, judge rules deny.
The body template receives:
examples/judges
holds provider configs.
Testing a bundle
rebuno policy test evaluates a bundle against cases and exits non-zero when a
decision does not match what the case expects.
shell.yaml with shell.policytest.yaml, or
wherever --cases points.
target is required and kind defaults to tool_call. subject and
subject_groups set the execution’s subject for subjects conditions; replayed
executions supply their own. expect is the
decision the case must produce and expect_rule the rule that must make it,
which catches a case still decided correctly but by the wrong rule. Omit both to
assert nothing. Unknown keys are rejected. A run also lists the rules no case
reached, which is how a rule shadowed by a broader one above it shows up.
history lists the allowed steps a case sees in every scope. Each takes
target, kind, args, result, and ago, a Go duration before the decision:
--target <name> --args '{...}' probes a single input instead of running cases,
printing its decision and rule.
A finished execution is the other source of cases. Replaying one feeds its
recorded steps back through a bundle and fails the steps a change would now
decide differently. The steps come from a running kernel, so replay names an
agent with --agent-id and reaches a kernel the way every command does
(CLI), or calls
POST /v0/policies/{agent_id}/test directly. Each replayed step
sees the history of its execution and session as it stood when it was decided.
--session, --since, and --limit replay many of the agent’s executions at
once, newest first, 100 by default and at most 1000:
Examples
Deny by default, allow only known tools:examples/policies/shell.yaml and
examples/rebuno.dev.yaml for working bundles.